SSZ (Simple Serialize) was coined by Vitalik Buterin in 2018 as a simpler
replacement for RLP in the Beacon Chain proposal.
Justin Drake, Ben Edgington, and
the research team iterated in the early eth2.0-specs repo; Drake’s
PR #71 is the first time
clients saw the SimpleSerialize name in code. The work later migrated into the current
consensus-specs/ssz folder and has stayed there ever since.
The official spec shows how every basic type is defined. The excerpt below is taken straight
from the GitHub file that client teams track:
ssz/simple-serialize.md
assert N in [8, 16, 32, 64, 128, 256]return value.to_bytes(N // BITS_PER_BYTE, "little")assert value in (True, False)return b"\x01" if value is True else b"\x00"
SSZ vs RLP
While both SSZ and RLP ultimately serialize data into bytes, their approaches and goals differ significantly. SSZ is designed around strict typing and fixed layouts to enable fast hashing and simple proofs, whereas RLP focuses on flexible, self-describing length-prefixed encodings optimized for general-purpose data serialization.
RLP encodes byte strings and nested lists with length prefixes; a single byte below 0x80 encodes itself without a prefix.
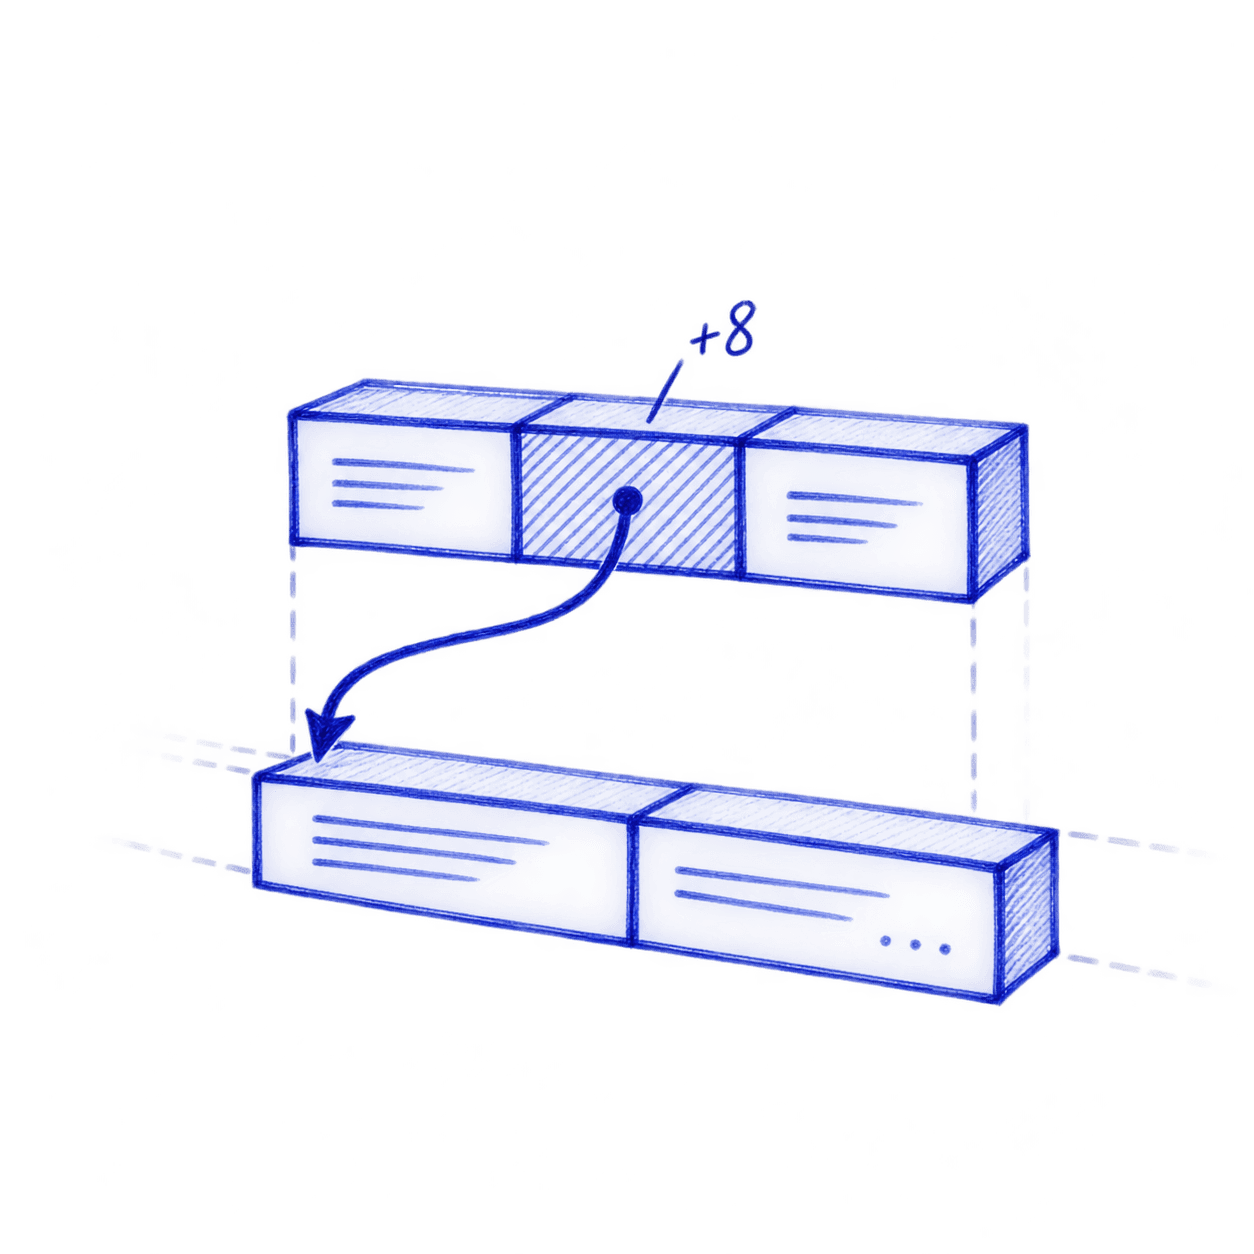
SSZ places fixed-size fields and 4-byte offsets in a fixed section, in field order. Each offset points to a variable-size field in the variable section.
This typed offset scheme enables constant-time access to variable fields and efficient hashing.
Encoding Multiple Bytes
For multi-byte strings, RLP adds a length prefix to indicate the payload size, while SSZ encodes the bytes directly according to its type definition. Adjust the slider below to see how each encoding handles strings of different lengths.
Encoding Multiple Bytes
HEX("abcdefghijklm")=0x6162636465666768696a6b6c6d
PBS("abcdefghijklm")=
0x0d6162636465666768696a6b6c6d
RLP("abcdefghijklm")=
0x8d6162636465666768696a6b6c6d
SSZ("abcdefghijklm")=0x6162636465666768696a6b6c6d
Key Differences
RLP: Adds a length prefix (8d) indicating total payload size. Total: 14 bytes
SSZ: Simply concatenates bytes without prefix. Total: 13 bytes
SSZ saves 1 byte(s) by omitting the length prefix, but requires the type definition (List[bytes, 32]) to know the structure.
Encoding Bytes Sequence
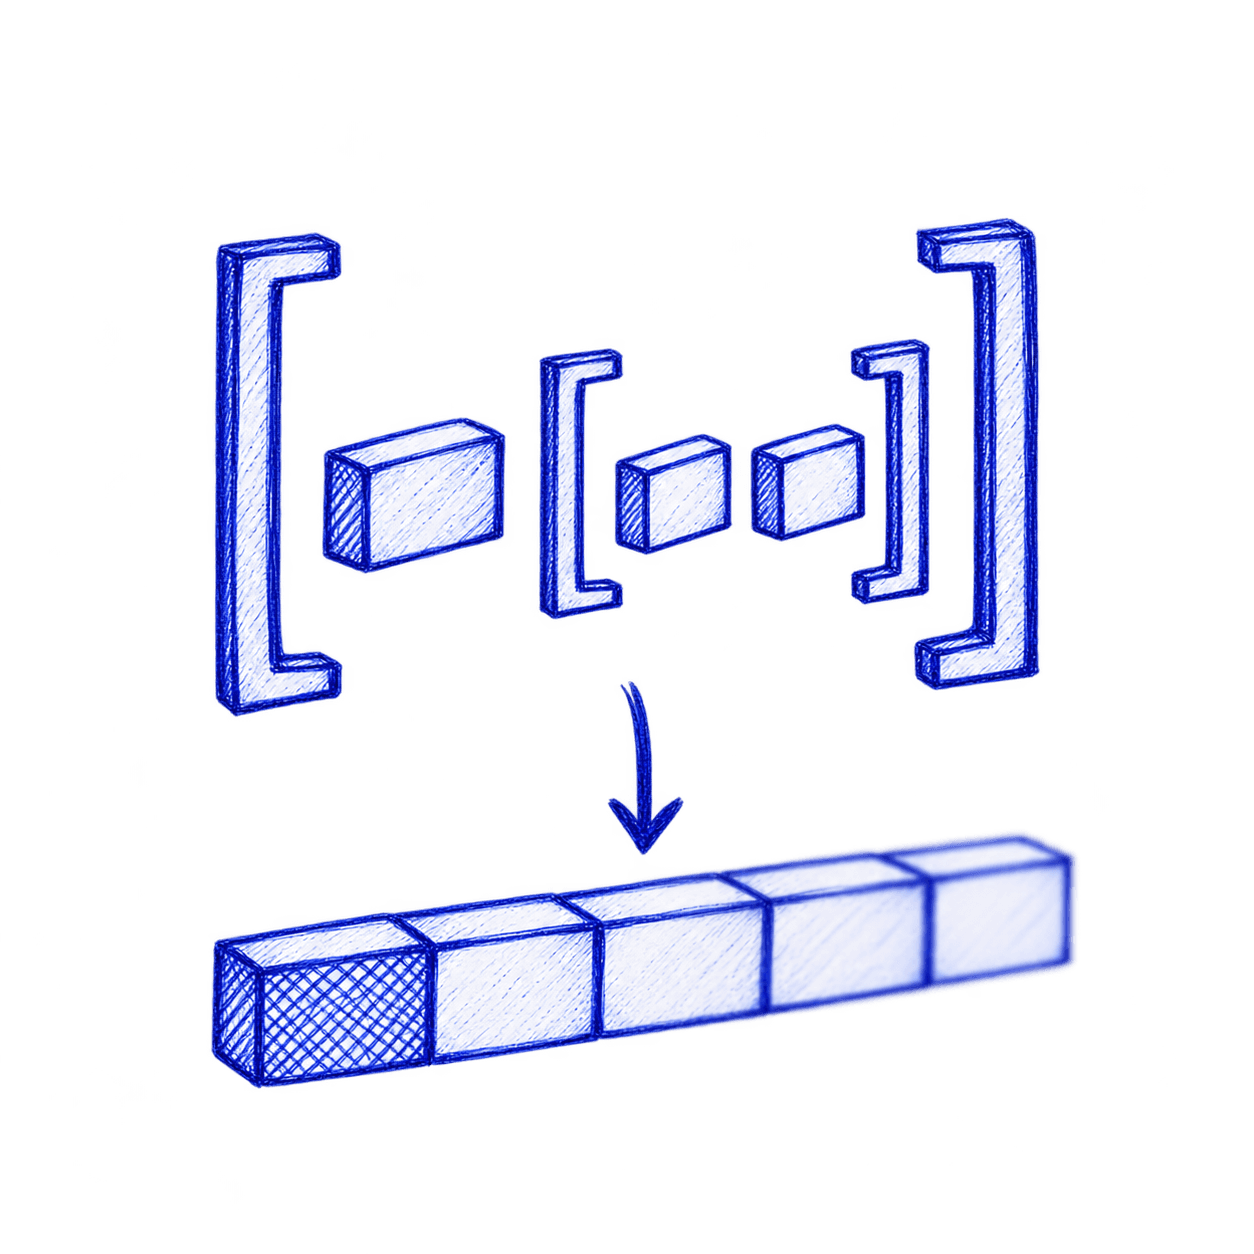
RLP wraps a list with a length prefix; each element may also need its own prefix. SSZ uses the element type to decide the layout. A list of fixed-size elements concatenates their encodings. A list of variable-size elements starts with one 4-byte offset per element, followed by their data.
In the figure, uint8 uses List[uint8, 6]; UTF-8 uses List[ByteList[64], 6], treating each string as a list of UTF-8 bytes. Select an input item or byte group to follow it through both encodings.
RLP
SSZList[uint8, 6]
RLP: 7 bytes. SSZ: 4 bytes.
SSZ is not always shorter. For List[uint8, 6], each value occupies one byte: [0, 127, 128, 255] takes 4 bytes in SSZ and 7 bytes in RLP. For the UTF-8 list ["0", "x", "build"], the data occupies 7 bytes, but SSZ also needs three 4-byte offsets: 12 + 7 = 19 bytes, compared with 9 bytes in RLP. The offsets preserve the boundaries between variable-size elements.
The 6 in these types is a maximum item count, not a stored count or reserved space. Likewise, ByteList[64] permits up to 64 bytes per item without padding each item to 64 bytes. For this list of byte lists, the serialized length is 4 × item count + total data bytes. These totals count serialized bytes, not Merkle-tree padding or the length mixed into a list's hash-tree root.
The integer and text modes also distinguish zero: RLP's integer convention encodes zero as the empty byte string (80), while SSZ uint8 encodes it as 00. The UTF-8 character "0" is 30 in both formats. An empty input represents an empty list; enter "" in UTF-8 mode for one empty string.
Ethereum uses RLP primarily for the execution layer, encoding transactions and state data, where flexibility is key. SSZ is the backbone of the consensus layer, chosen for its deterministic layouts and suitability for light-client proofs.
Layout
Unlike RLP, SSZ does not encode type information in the byte stream. The layout (type definition) is separate from the encoded data and must be known in advance by both encoder and decoder.
Where type definitions are stored:
Consensus specifications: The Ethereum consensus specs repository defines all SSZ types used in the Beacon Chain (e.g., BeaconBlock, Attestation, Validator).
Client code: Each client implementation (Prysm, Lighthouse, Teku, etc.) includes these type definitions in their codebase.
Protocol documentation: The official SSZ spec documents the encoding rules, while consensus specs define the specific types.
Why this design?
Efficiency: No overhead from encoding type metadata in every message.
Determinism: All clients use identical type definitions, ensuring identical encodings.
Verification: Light clients can verify data without knowing the full type, using Merkle proofs that rely on fixed layouts.
When you see List[uint8, 8] or Vector[uint16, 4], these are part of the type definition, not the encoded bytes. The bytes themselves contain only the data, arranged according to the predefined layout.
Primitives
Unsigned ints are little-endian and fixed width: uint8 → 1 byte, uint16 → 2 bytes, uint32 → 4 bytes.
Booleans still use a byte so hashes stay aligned (0x00 for false, 0x01 for true).
Scalar → bytes
Input 2 bytes, little-endian
Encoded Bytes 2 bytes
0x010x00
Switch the type selector, nudge the value, and notice how the least-significant byte always appears first.
Vectors
Vectors are arrays with the element count baked into the type. For fixed-size elements such as uint16, the encoder places their encodings back-to-back, without headers or lengths. Vectors of variable-size elements use offsets, just as lists of variable-size elements do.
Changing any slot only touches its two bytes. The total stays at 8 bytes because 4 * uint16 never changes.
Lists
Lists have a variable item count and a maximum defined by their type. For fixed-size elements, divide the serialized byte count by the element width to recover the item count. In the uint8 example below, each element occupies one byte. If the list is a field in a container, the container stores an offset to its data.
The demo container has version, flag, count, and two lists. As you extend a list:
The payload always starts at byte 13, immediately after the fixed section. Extending it shifts the proofs and updates the proofs offset; extending proofs changes only the total length.
The variable section grows by exactly the number of bytes you added.
The offset beside each input matches its start position in the continuous byte strip. Select either to highlight the corresponding field. Fixed fields and the full serialization remain expandable.